
Commerce Platform Modernization
Independently deployable services and Kafka event pipelines sustaining 99.95% availability.
- Role
- Senior engineer · services and event pipelines
- Core stack
- KafkaMicroservicesVersioned APIsSchema validationAutoscaling
Overview
Modernized a client commerce platform into independently deployable services, with event-driven order and inventory processing built to recover cleanly from bad data.
The platform had to evolve without breaking existing clients or data, while order and inventory processing needed to be reliable, observable, and recoverable when malformed events appeared.
Product walkthrough
The flow, screen by screen
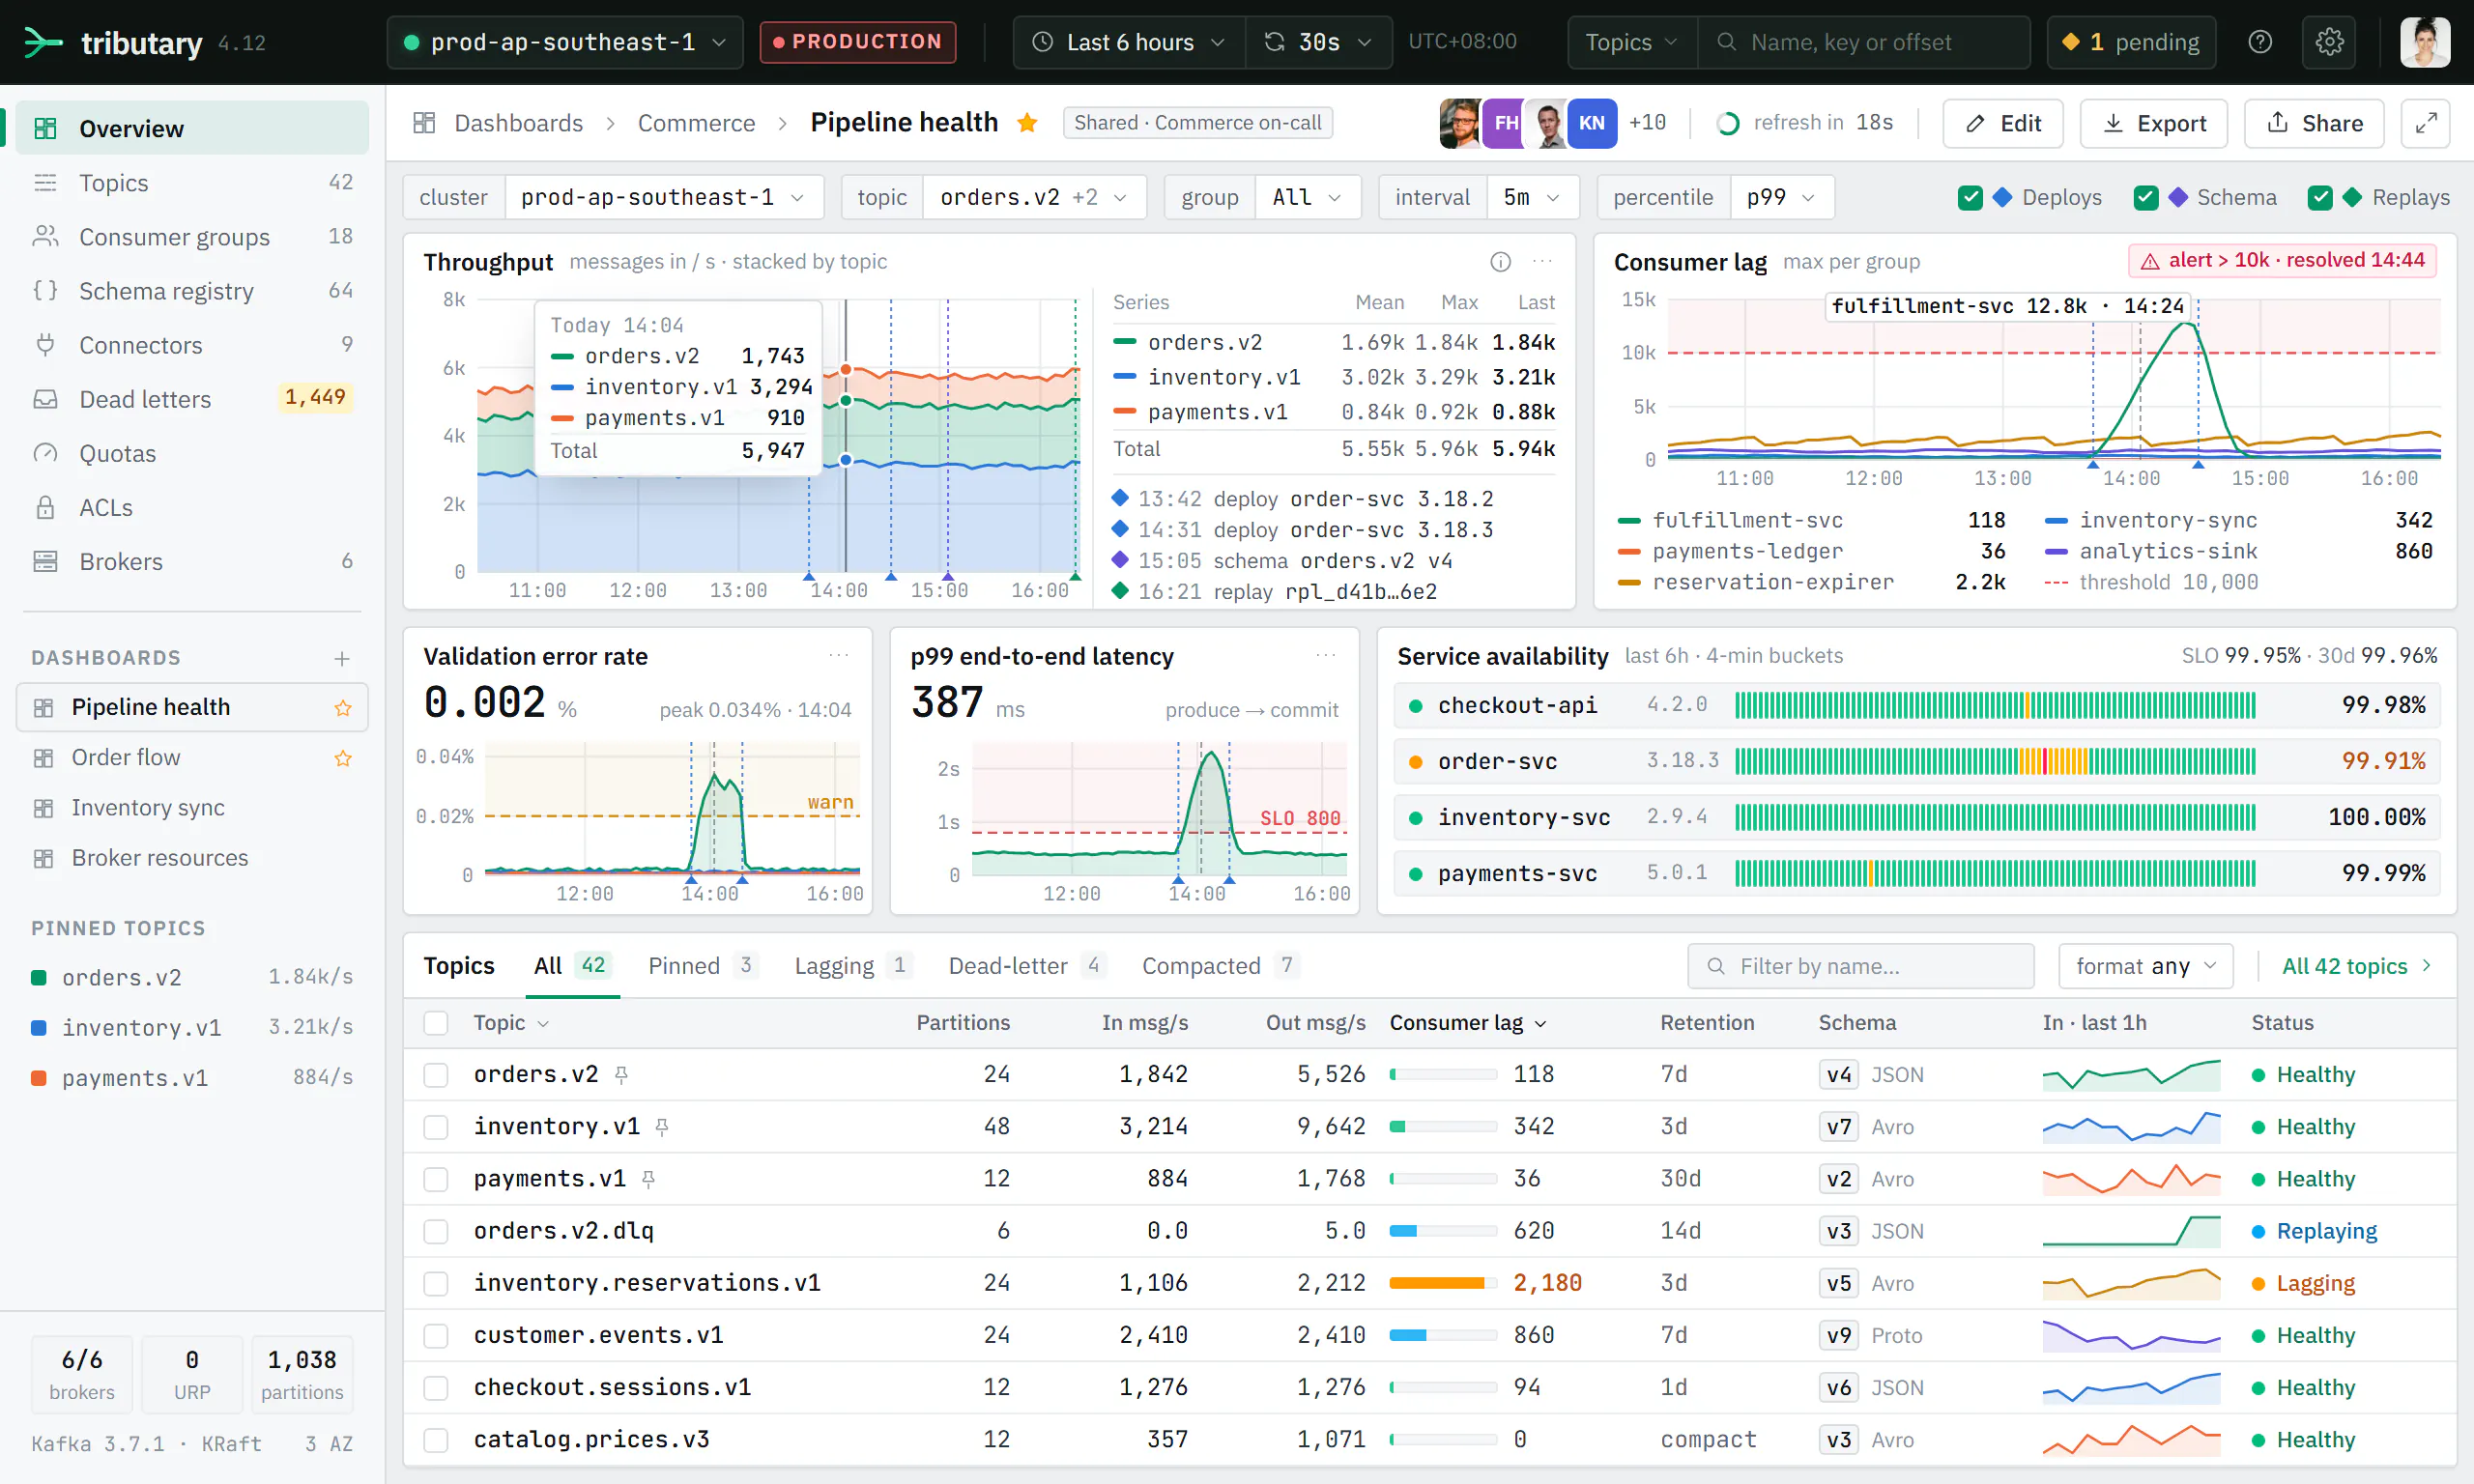
Pipeline health. Throughput, consumer lag, and error rates for order and inventory topics, alongside the availability of the core services.
Approach
- 01Split the platform into independently deployable services with clear domain boundaries and versioned APIs.
- 02Used backward-compatible database migrations so services and schemas could change without downtime.
- 03Developed Kafka workflows for order and inventory processing with schema validation, dead-letter queues, and event-replay tooling.
- 04Improved autoscaling and database queries to reduce cloud infrastructure costs.
- 05Standardized release checks and technical reviews across a six-person engineering team.
Key decisions
Versioned APIs at the boundary
Consumers can migrate at their own pace while services evolve independently.
Dead-letter queues with replay
Bad events are isolated instead of blocking the stream, then replayed once fixed, with no data loss.
Backward-compatible migrations
Expand-then-contract schema changes let old and new code run side by side during deploys.
Outcomes
- More consistent deployments and incident response across the team.
- Recoverable event processing through schema validation and replay.
- Kafka
- Microservices
- Versioned APIs
- Schema validation
- Autoscaling
- SQL
- CI/CD
Working on something similar?
I work with clients worldwide, across any time zone. Tell me what you're building.